Lifetime VPS Europe
 Lifetime VPS Asia
 Lifetime WooCommerce Hosting
 Lifetime Hosting
 Lifetime Game Dedicated Servers
 Chicago, US
 Tokyo, Japan
 Singapore
 Hong Kong
 Seoul, South Korea
 Amsterdem, Netherlands
 London, UK
 Stockholm, Sweden
 Oslo, Norway
 Vienna, Austria
 Zurich, Switzerland
 Sydney, Australia
 Wordpress Hosting
 VPS Hosting
 DDOS Protection
 Submit Ticket
 Full Management
 Guides
 Videos and Podcasts
 Discover Creative Ideas
 Voxfor Autonomous AI Workers
 Voxfor Mega Menu
 Voxfor Advanced Price Management For WooCommerce
 Voxfor Secure Live Chat and AI Support
 Voxfor Multilanguage
 Voxfor AI Content Summary
 Voxfor Autopilot
AI & Machine Learning
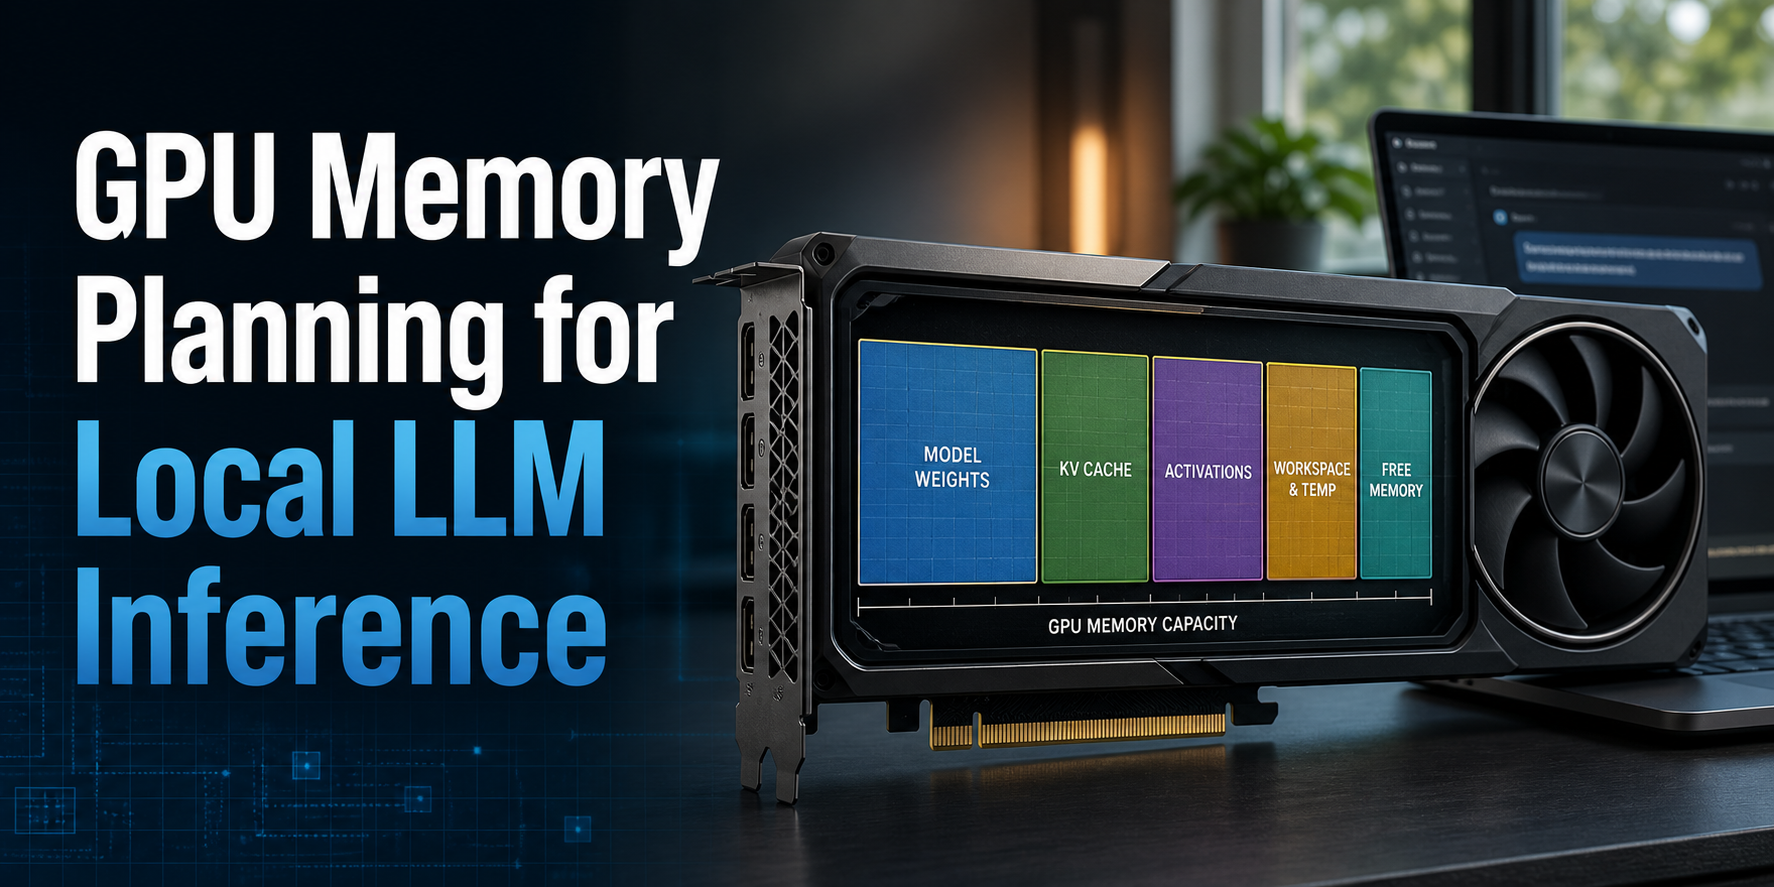
GPU Memory Planning for Local LLM Inference
GPU memory planning starts with one equation: required VRAM = model weights + KV cache + runtime reserve. A checkpoint that fits…

Practical guides, fresh perspectives and technical know-how from Voxfor.
GPU memory planning starts with one equation: required VRAM = model weights + KV cache + runtime reserve. A checkpoint that fits…