Lifetime VPS Europe
 Lifetime VPS Asia
 Lifetime WooCommerce Hosting
 Lifetime Hosting
 Lifetime Game Dedicated Servers
 Chicago, US
 Tokyo, Japan
 Singapore
 Hong Kong
 Seoul, South Korea
 Amsterdem, Netherlands
 London, UK
 Stockholm, Sweden
 Oslo, Norway
 Vienna, Austria
 Zurich, Switzerland
 Sydney, Australia
 Wordpress Hosting
 VPS Hosting
 DDOS Protection
 Submit Ticket
 Full Management
 Guides
 Videos and Podcasts
 Discover Creative Ideas
 Cybersecurity Services
 Voxfor Mega Menu
 Voxfor Advanced Price Management For WooCommerce
 Voxfor Secure Live Chat and AI Support
 Voxfor Multilanguage
 Voxfor AI Content Summary
 Voxfor Autopilot
AI & Machine Learning
How Long Should Ollama Keep a Model Loaded?
Ollama can retain a model after a request, let it expire, or unload it immediately. Those choices trade warm-request latency for memory…

Explore the rapidly evolving realm of artificial intelligence, delving into cutting-edge advancements, practical use cases, and expert insights to harness AI’s transformative potential across various industries.
Ollama can retain a model after a request, let it expire, or unload it immediately. Those choices trade warm-request latency for memory…
The reproduced stream completed its HTTP body and ended with data: [DONE], yet it contained zero usage chunks. That is a successful…
Repository coordinates on Hugging Face are a mutable address, not a release identity. If a service downloads main during every cold start,…
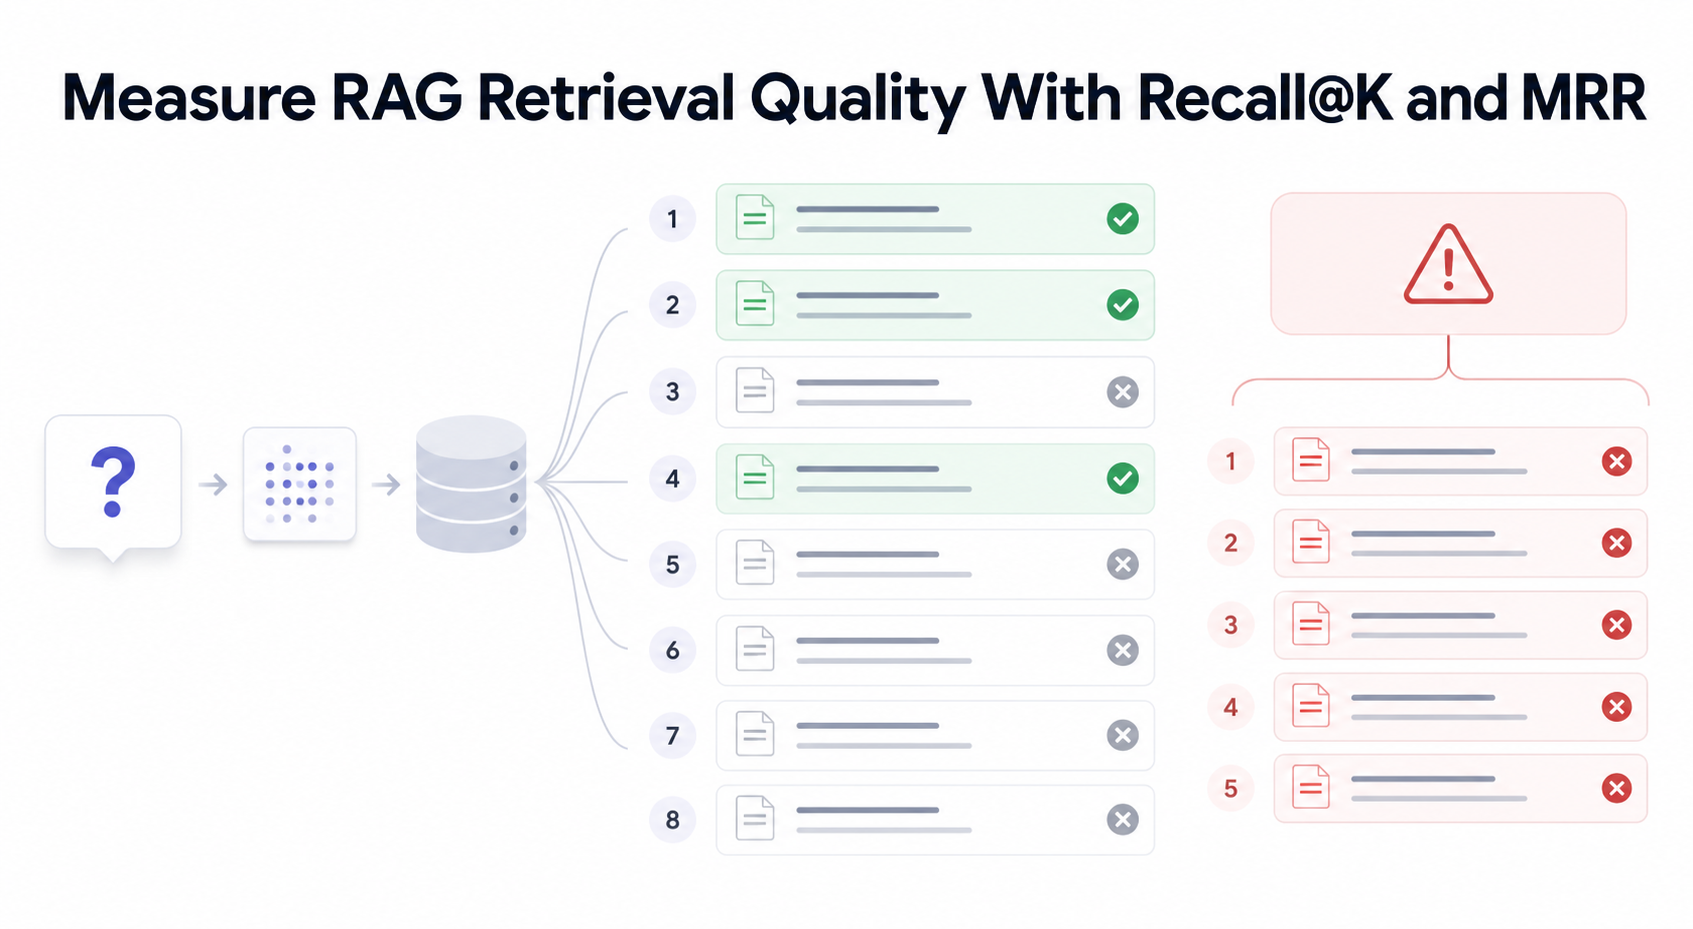
A fluent answer cannot prove that Retrieval-Augmented Generation found the right evidence. The generator may write confidently from incomplete context, while a…
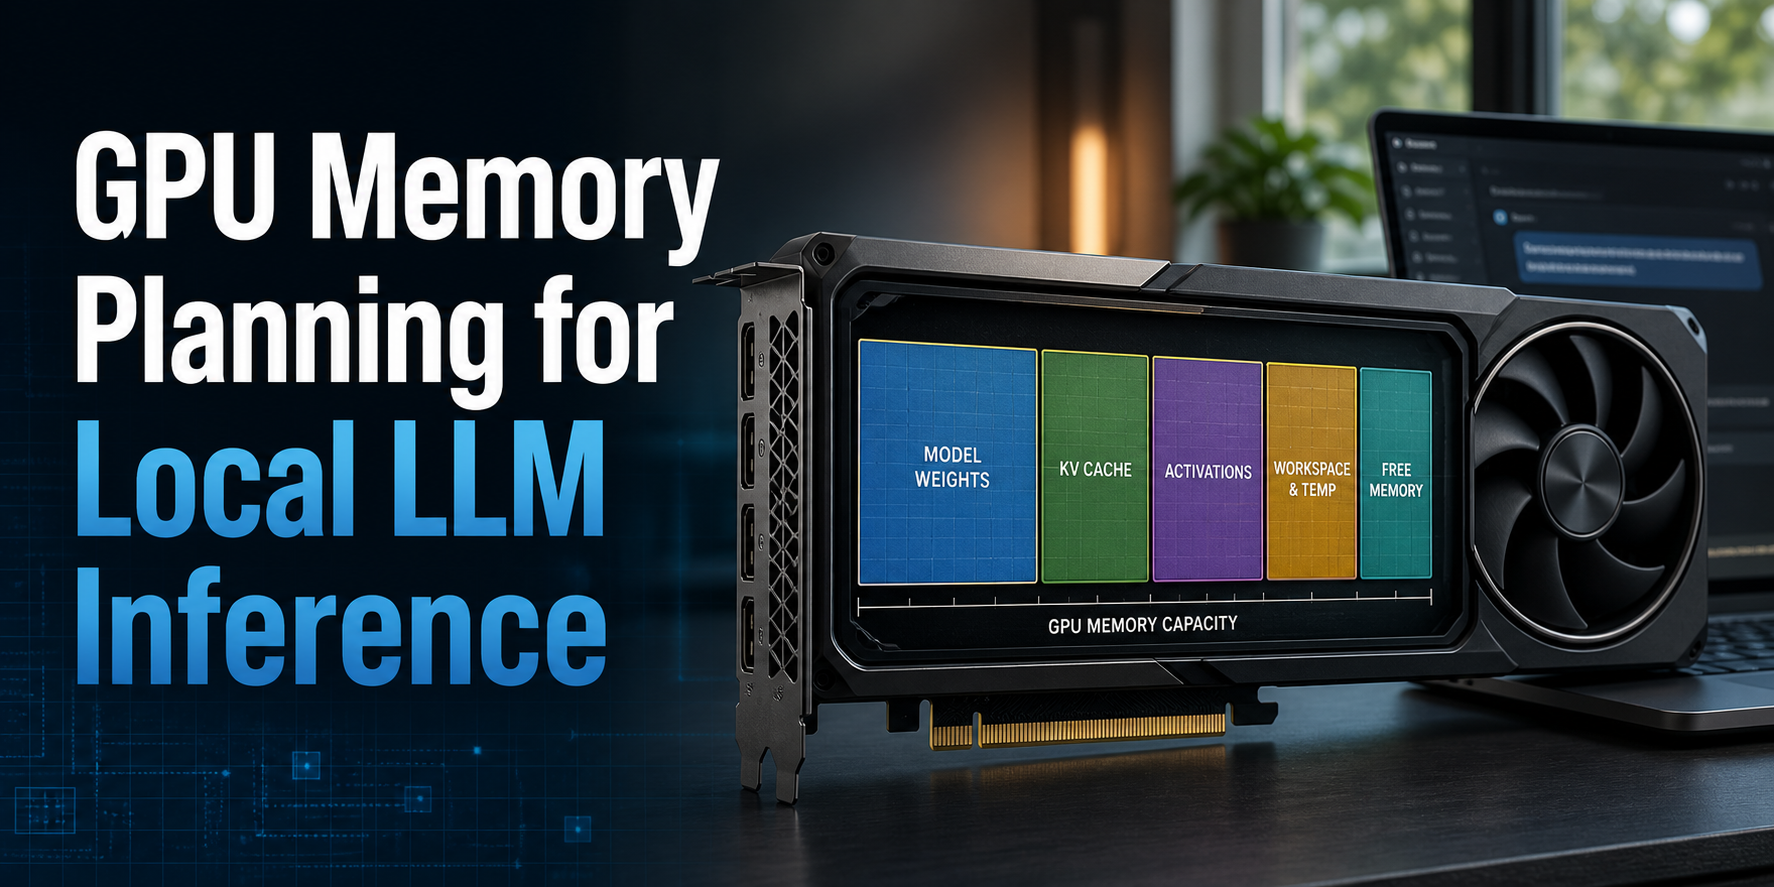
GPU memory planning starts with one equation: required VRAM = model weights + KV cache + runtime reserve. A checkpoint that fits…
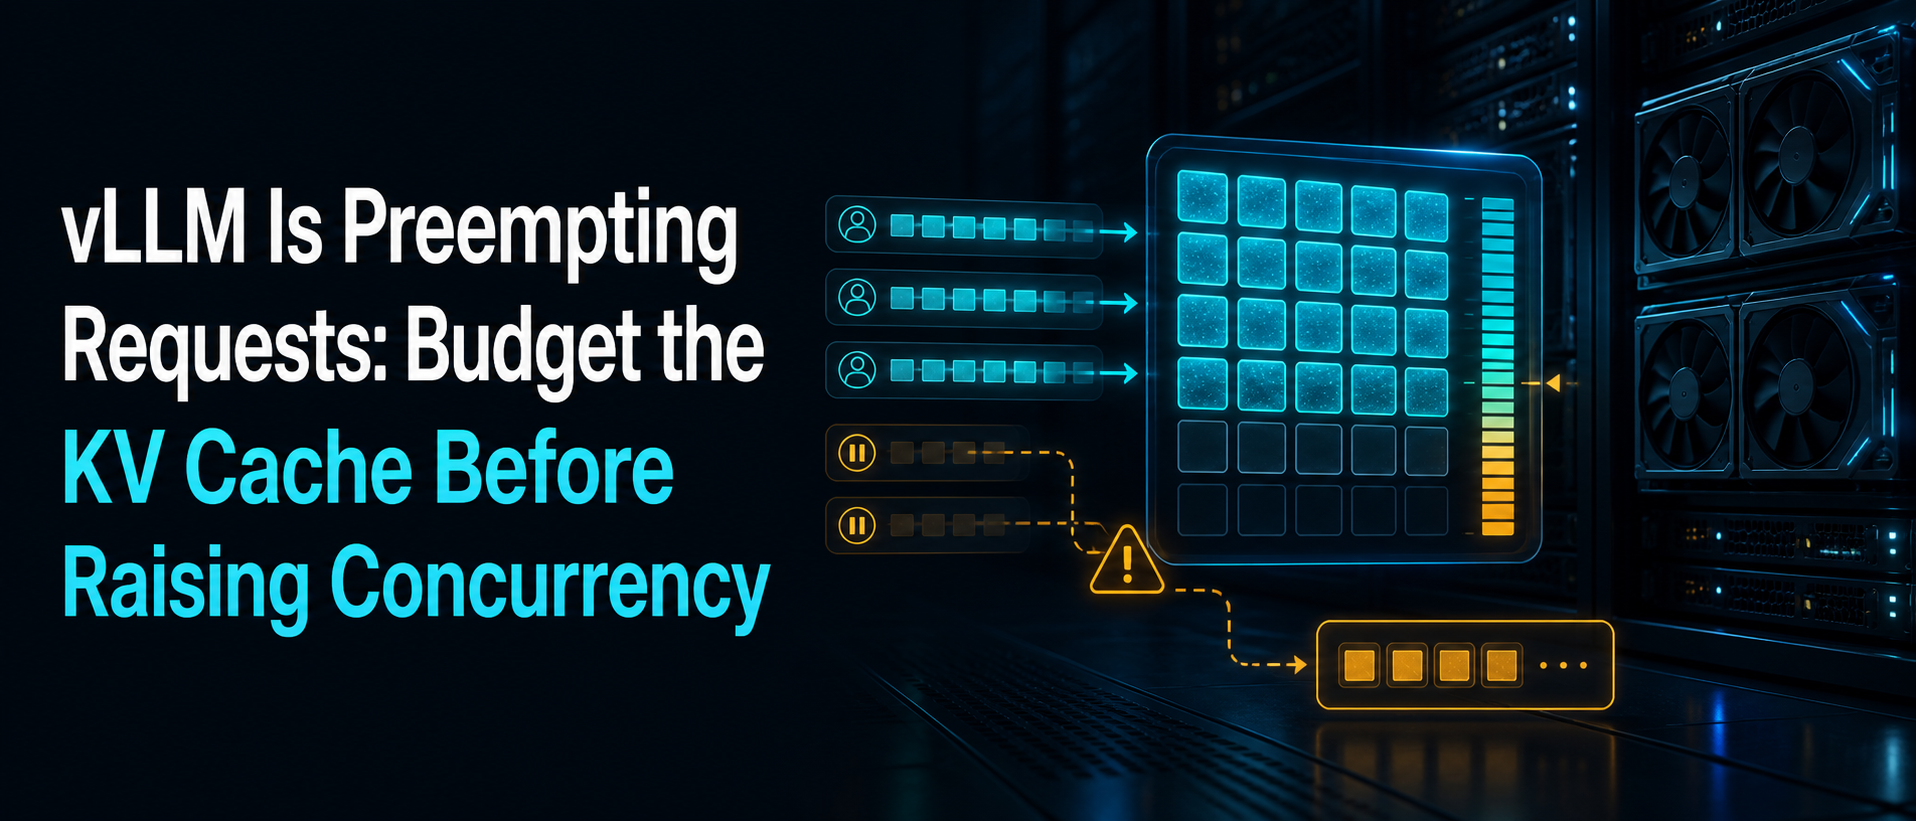
Sequence group ... is preempted by PreemptionMode.RECOMPUTE mode because there is not enough KV cache space. That warning does not mean the…
An AI agent asks a tool to create a DNS record. The provider accepts the change, but the HTTP response disappears before…
Sticky sessions are not a universal MCP requirement anymore. A remote Model Context Protocol client speaking 2026-07-28 sends self-describing requests that may…
Raw vector bytes are only the first line in a Qdrant storage budget. A collection also carries payload, payload indexes, vector indexes,…
nvidia-smi can show a healthy GPU while an Ollama request still runs partly—or entirely—on CPU. That contradiction does not have one universal…
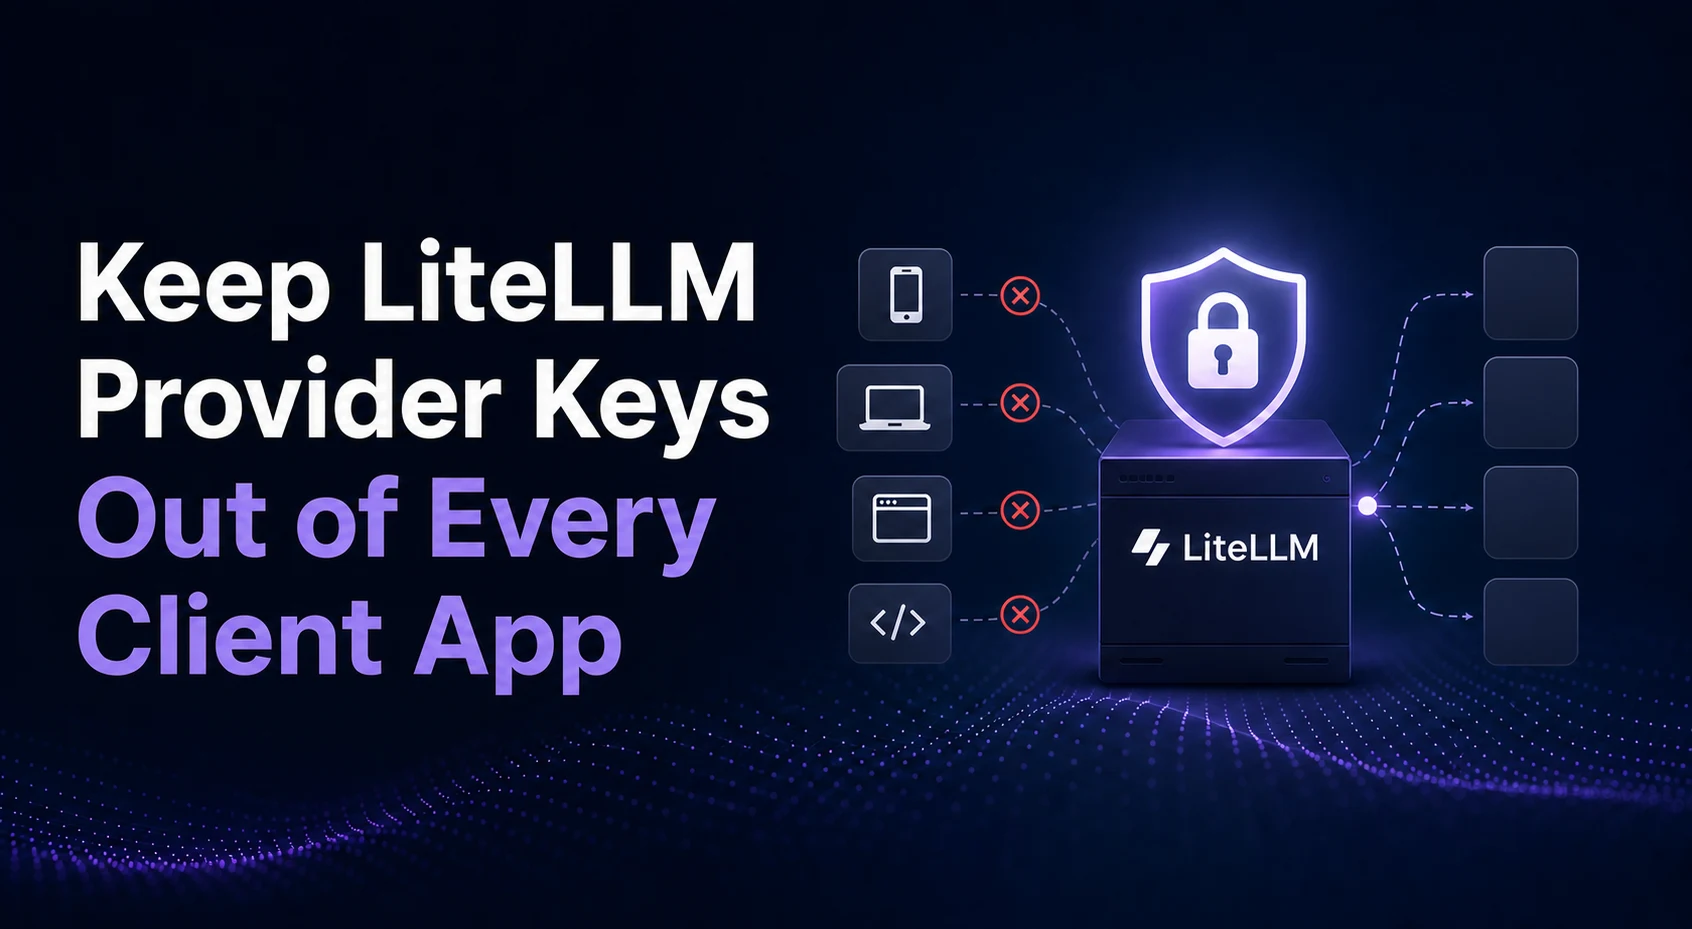
LiteLLM Proxy can give several applications one OpenAI-compatible endpoint without distributing the underlying provider credentials. The safe pattern is to keep the…
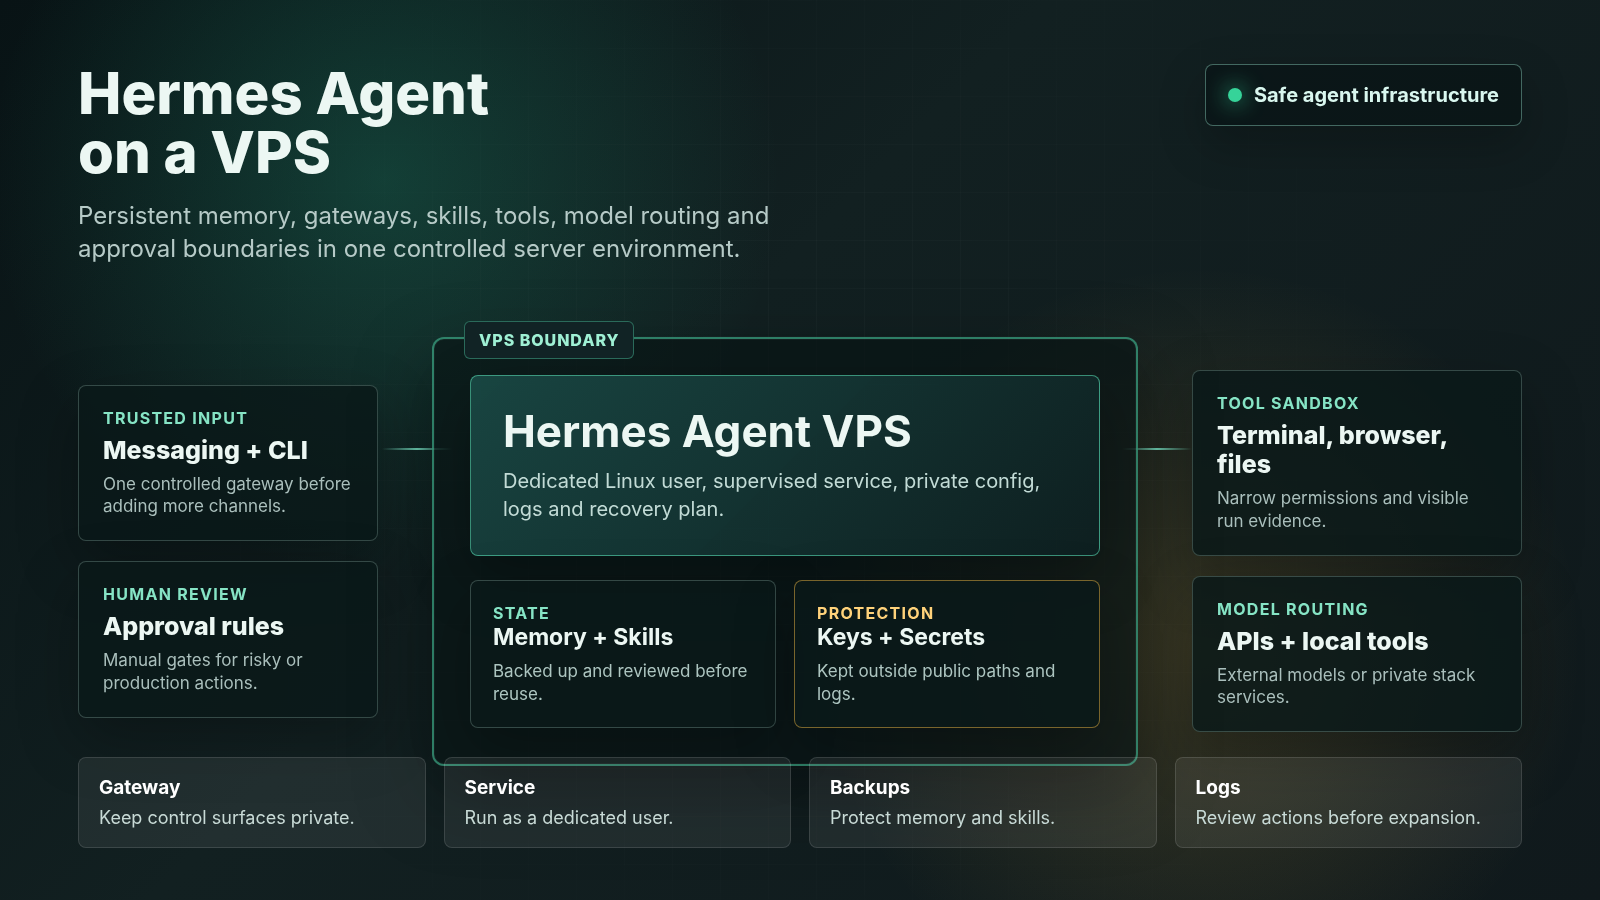
How to Host Hermes Agent on a VPS Safely Hermes Agent becomes more useful when it is treated as a small operating…
A transparent technical review for Voxfor readers of Algorithm R8, Netanel Siboni's fail-closed verification and provenance system for cloud-quantum experiments.
Run AI agents on a secure VPS workspace with uptime, privacy, tool access and automation control for serious workflows.
Deploy an AI agent on a VPS with systemd or Docker, secure API keys, add logs and monitoring, and choose the right…
Claude Opus 4.8 is the latest upgrade in Anthropic Opus model family, and it arrives at a time when businesses, developers, content…
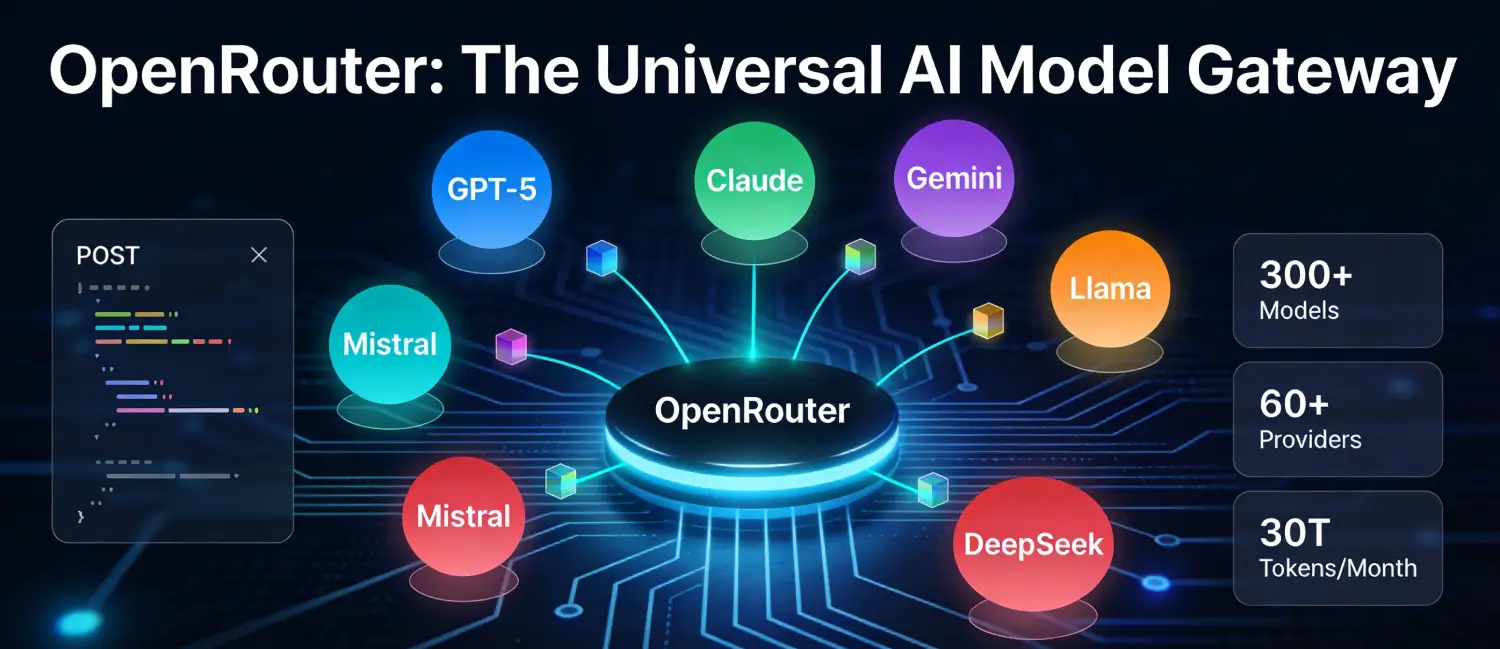
OpenRouter is a unified API platform that provides developers and businesses with access to hundreds of large language models (LLMs) from dozens…
Terafab is a planned vertically integrated semiconductor fabrication complex, jointly developed by Tesla, SpaceX, and xAI, officially announced by Elon Musk on…
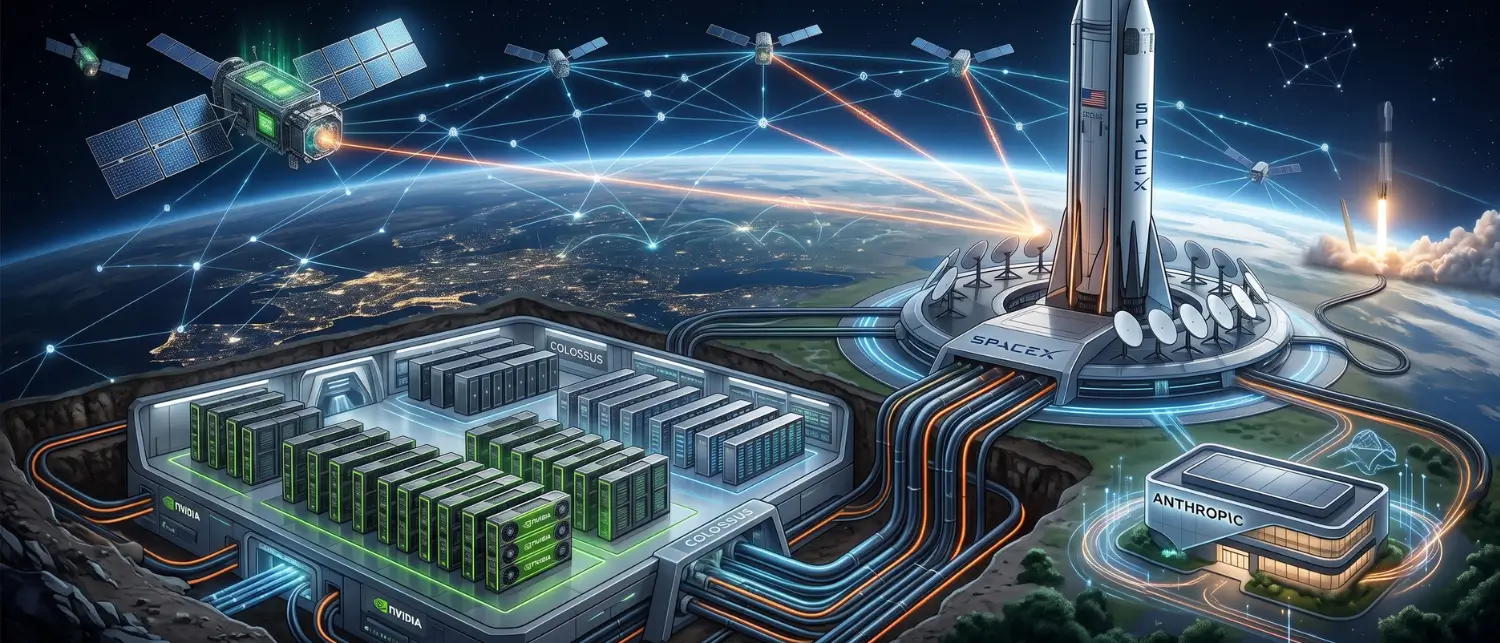
Anthropic's recent deal with SpaceX foraccess to all compute capacity at SpaceX's Colossus 1 data center, over 220,000 NVIDIA GPUs delivering 300+…
The artificial general intelligence race is no longer a theoretical debate. Elon Musk predicted AGI could arrive as early as 2026. OpenAI…
Move AI MVPs from localhost to production with managed VPS planning, security hardening, deployment workflows, backups, logs, and handover.