Lifetime VPS Europe
 Lifetime VPS Asia
 Lifetime WooCommerce Hosting
 Lifetime Hosting
 Lifetime Game Dedicated Servers
 Chicago, US
 Tokyo, Japan
 Singapore
 Hong Kong
 Seoul, South Korea
 Amsterdem, Netherlands
 London, UK
 Stockholm, Sweden
 Oslo, Norway
 Vienna, Austria
 Zurich, Switzerland
 Sydney, Australia
 Wordpress Hosting
 VPS Hosting
 DDOS Protection
 Submit Ticket
 Full Management
 Guides
 Videos and Podcasts
 Discover Creative Ideas
 Voxfor Autonomous AI Workers
 Voxfor Mega Menu
 Voxfor Advanced Price Management For WooCommerce
 Voxfor Secure Live Chat and AI Support
 Voxfor Multilanguage
 Voxfor AI Content Summary
 Voxfor Autopilot
AI & Machine Learning
How Long Should Ollama Keep a Model Loaded?
Ollama can retain a model after a request, let it expire, or unload it immediately. Those choices trade warm-request latency for memory…

Practical guides, fresh perspectives and technical know-how from Voxfor.
Ollama can retain a model after a request, let it expire, or unload it immediately. Those choices trade warm-request latency for memory…
The reproduced stream completed its HTTP body and ended with data: [DONE], yet it contained zero usage chunks. That is a successful…
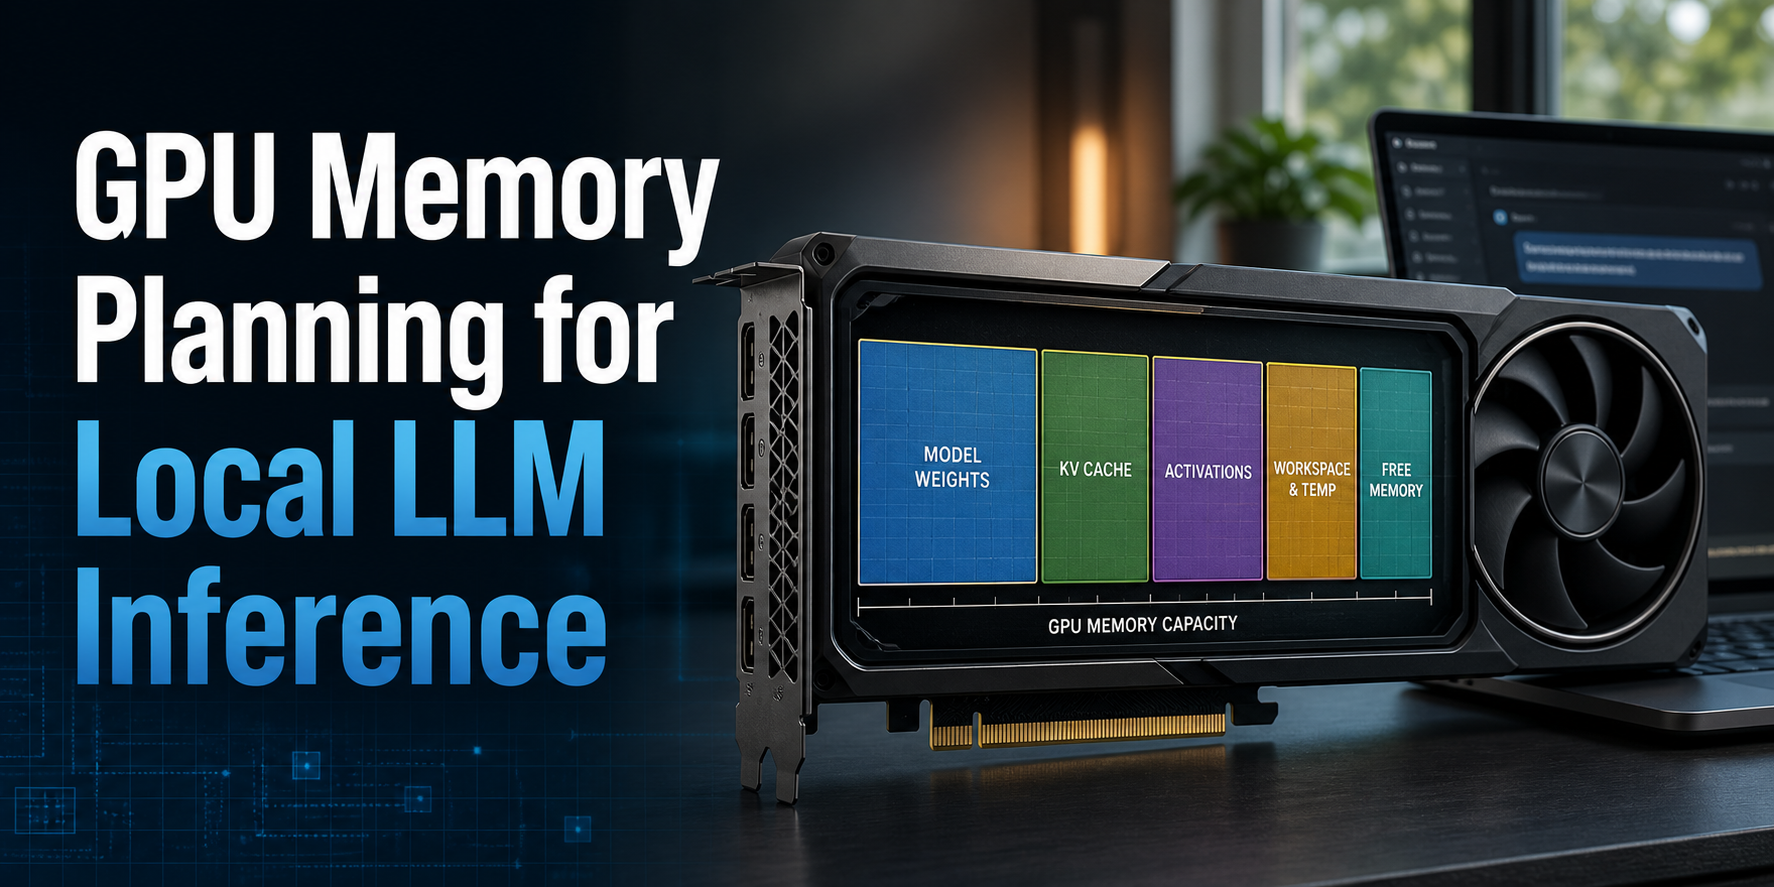
GPU memory planning starts with one equation: required VRAM = model weights + KV cache + runtime reserve. A checkpoint that fits…
Sticky sessions are not a universal MCP requirement anymore. A remote Model Context Protocol client speaking 2026-07-28 sends self-describing requests that may…
nvidia-smi can show a healthy GPU while an Ollama request still runs partly—or entirely—on CPU. That contradiction does not have one universal…
Plan VPS specs for Ollama and local LLMs with RAM, CPU, NVMe storage, RAG sizing, CPU versus GPU expectations, and safe API…
In the past couple of years, Artificial Intelligence has transitioned from a theoretical playground to a mandatory enterprise tool. However, a significant…
The AGI Race: Four AI Frontiers Competing for Intelligence Supremacy in 2025 The artificial intelligence landscape has erupted into chaos. Within a…
Compare dedicated GPU servers, cloud GPU, hybrid GPU, and standard VPS orchestration for AI, ML, rendering, data movement, security, and workload planning.